Cloud Architecture
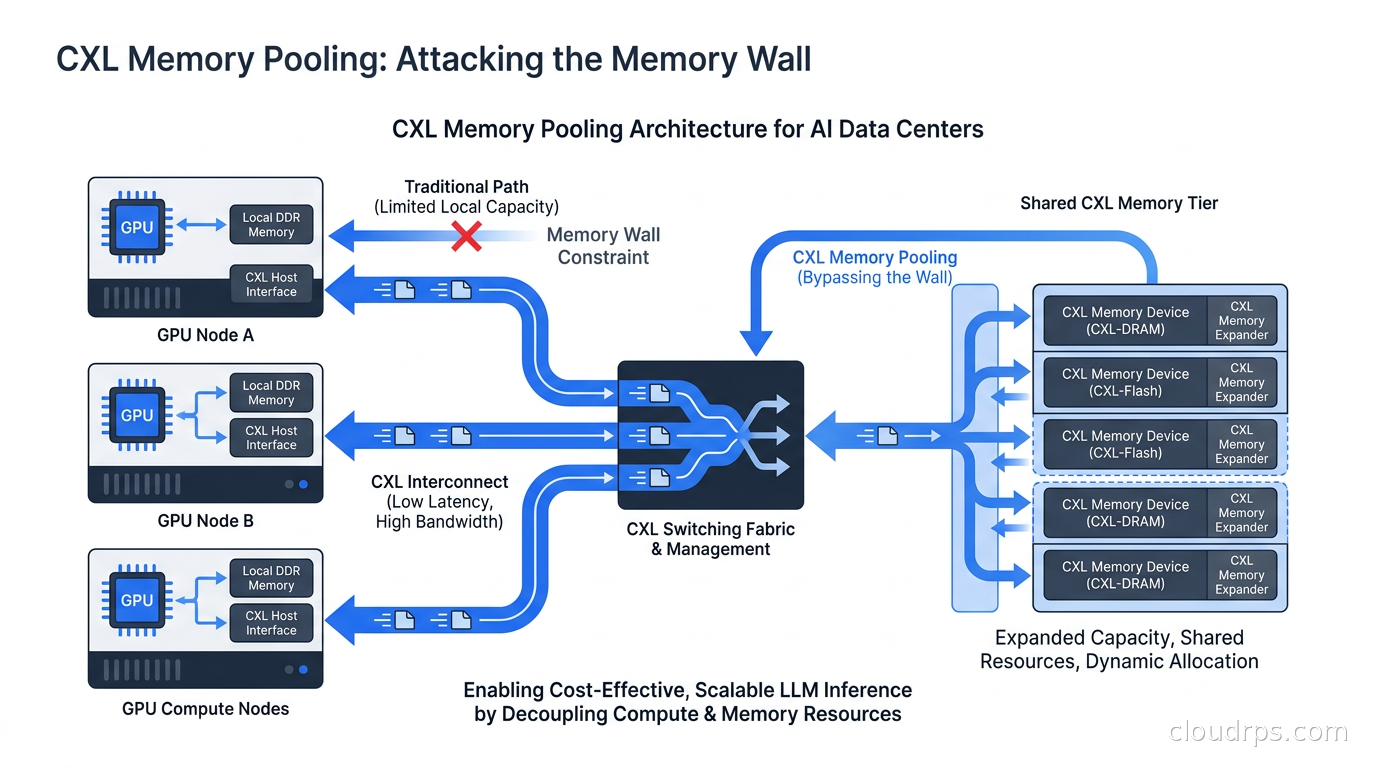
CXL Memory Pooling for AI Data Centers: How Compute Express Link Is Attacking the Memory Wall That Keeps Your LLM Inference Expensive
A principal cloud architect breaks down CXL memory pooling, how it solves the KV cache bottleneck in LLM inference, and what the Marvell Structera and Azure CXL deployments mean for your infrastructure decisions.