Cloud Architecture
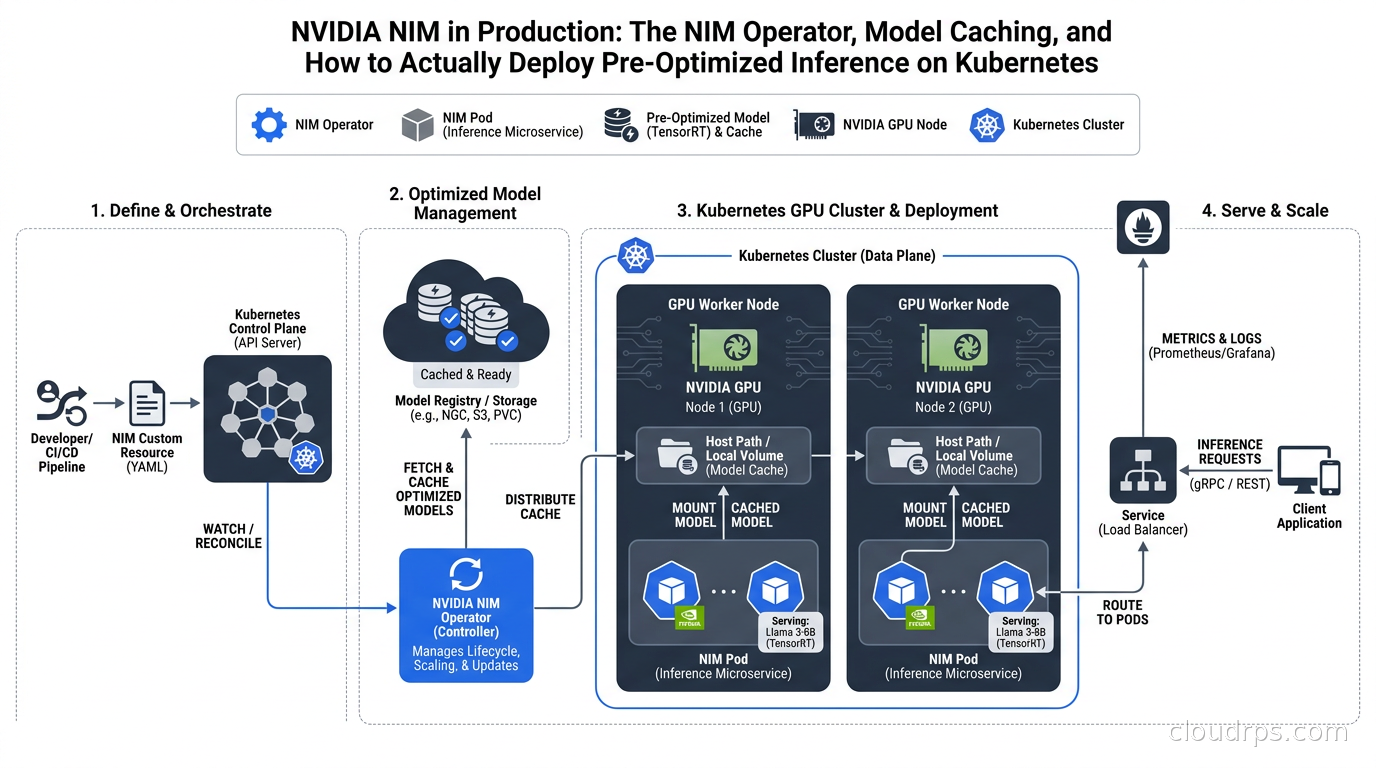
NVIDIA NIM in Production: The NIM Operator, Model Caching, and How to Actually Deploy Pre-Optimized Inference on Kubernetes
A principal cloud architect's guide to NVIDIA NIM microservices in production: how the NIM Operator works, when NIM beats raw vLLM, and the caching and scaling patterns that matter.